
Notes from the racks
Every article tagged .
Written by platform engineers
Field-tested, not theoretical
New analysis every month
5 articles
 How-to/
5 min read
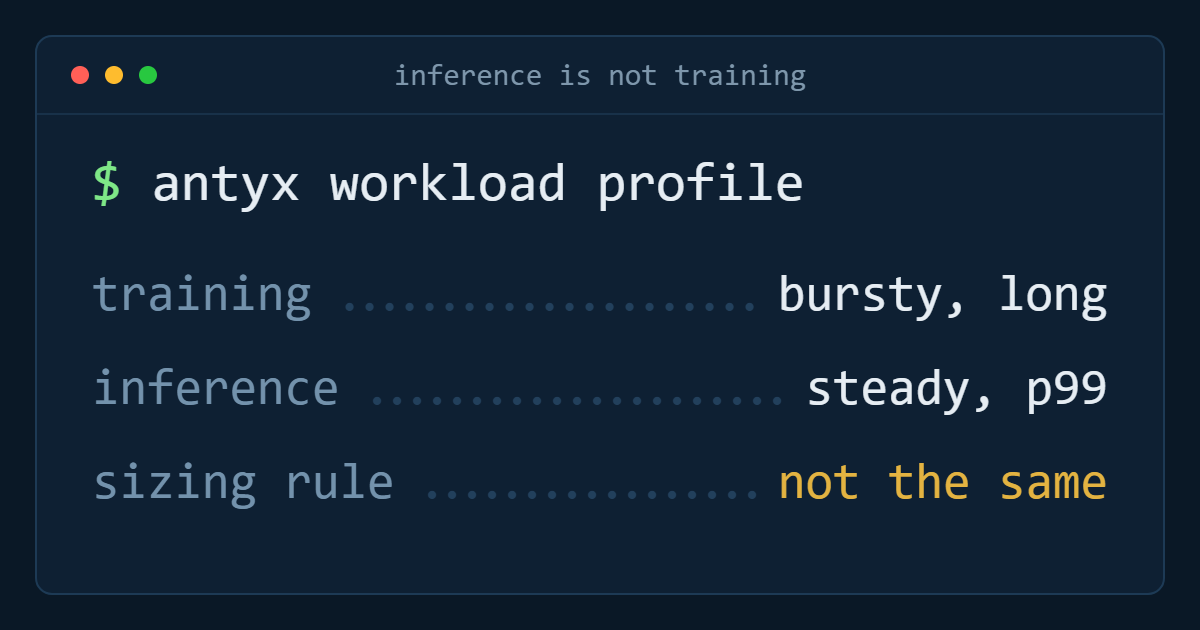
Inference is not training: sizing for serving, not for the run
Training is throughput-bound and batch-friendly. Serving is latency-bound and bursty. Sizing one like the other is how GPU bills get strange.
Sep 2, 2026
 compliance/
5 min read
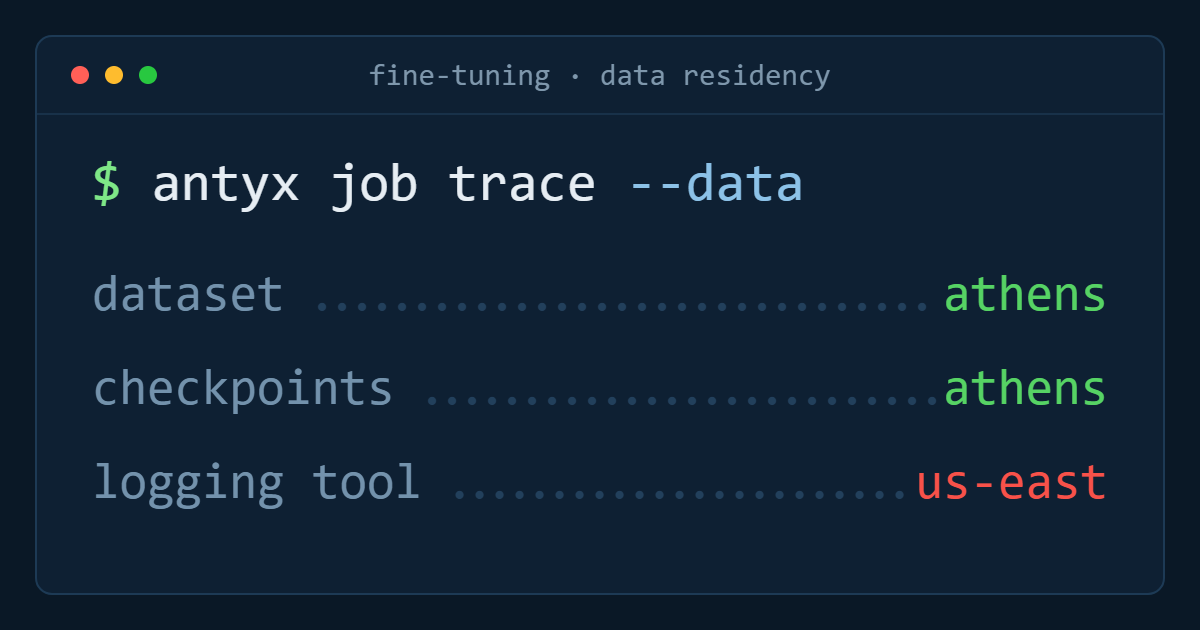
Fine-tuning an open-weight model in one EU region
Keeping a fine-tune in one jurisdiction is an operations problem, not a legal one. The seven places training data actually leaves — and how to close them.
Sep 2, 2026
 How-to/
6 min read
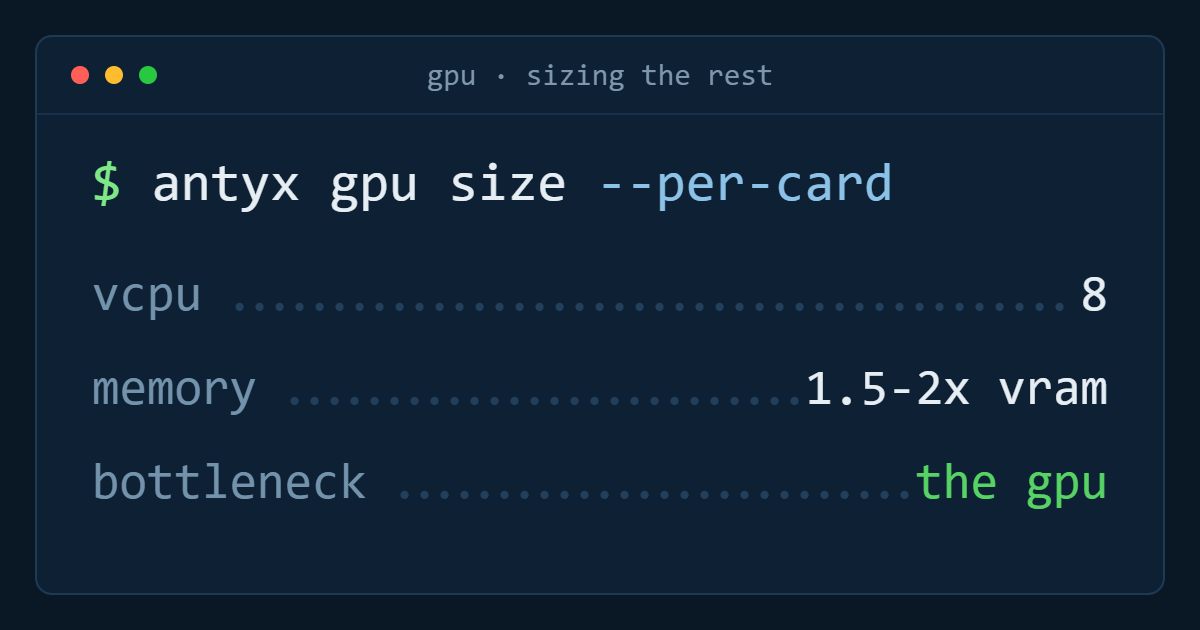
Sizing a GPU instance: what to put around the accelerator
A GPU is only as fast as the CPU, memory and disk feeding it. How to size the rest of the instance so the accelerator is the bottleneck.
Sep 2, 2026
 Cost/
6 min read
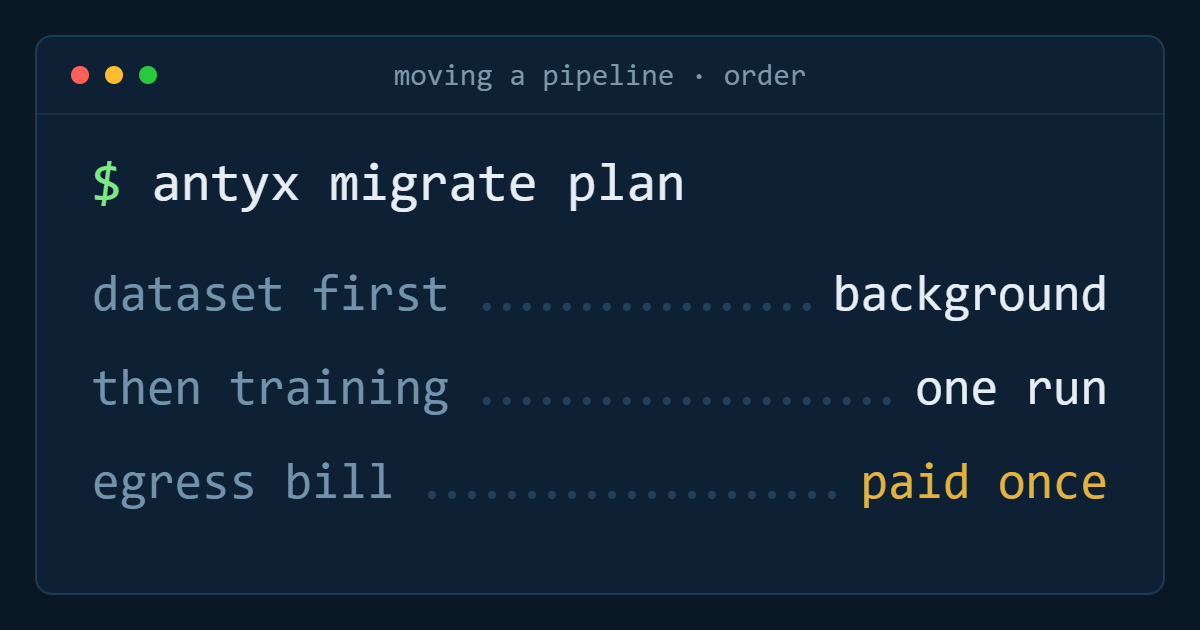
Moving a training pipeline off a hyperscaler without stopping it
You cannot pause research for a migration. A sequenced move that keeps runs going: data first, then one reproduced run, then a shadow period.
Sep 2, 2026
 Cost/
5 min read
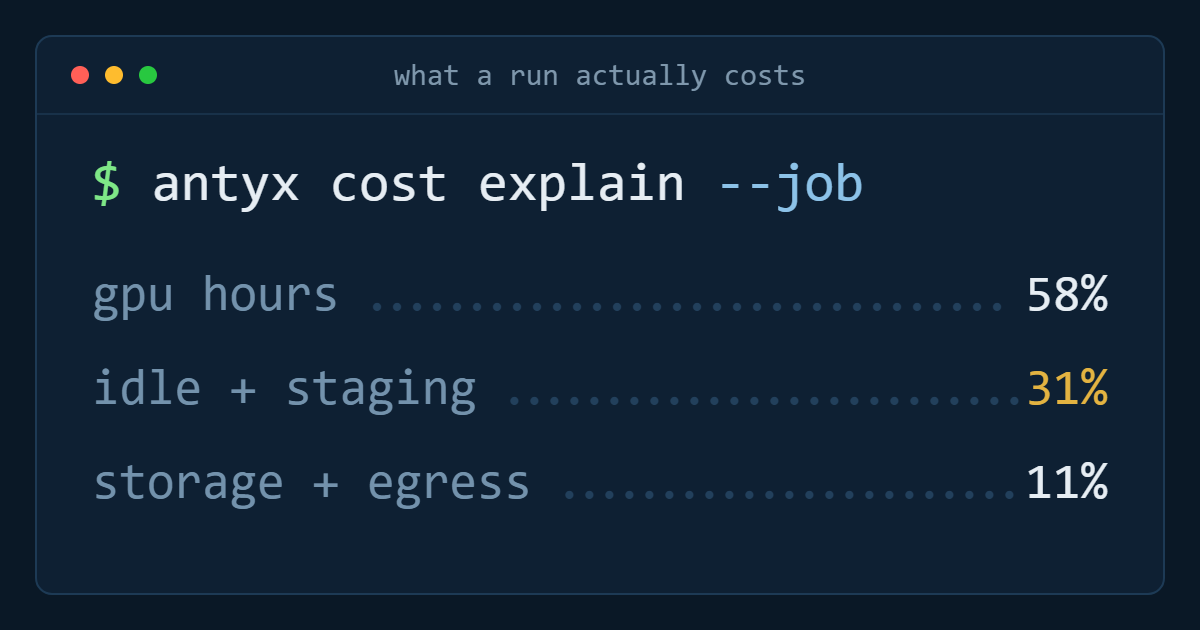
What a training run actually costs
The hourly rate is rarely more than half the bill. The five line items that make up the rest, and how to measure cost per completed run.
Sep 2, 2026