
Cloud GPUs for AI, rendering and scientific computing
Accelerate the workloads that punish CPUs — model training, 3D rendering, video encoding and simulation — on GPU instances you rent by the month instead of buying by the rack.
Why teams choose cloud GPUs
Cutting-edge accelerators without the capital expenditure, the procurement lead time or the depreciation.
Accelerated computing
No hardware investment
High performance
Elastic scalability
Built for availability, not just peak throughput
Real-time visibility into every GPU you run
GPU instances are not generally available yet
Support for GPU instances is being introduced across our regions. Tell us what you plan to run and we will contact you when capacity opens in your region — waitlist accounts are allocated first.
- Regions
- Boston first, then Athens and Barcelona
- Billing
- Monthly, on the same invoice as the rest of your estate
- Pairs with
- Block Storage for datasets, Kubernetes for scheduling
- Config
- vCPU, memory and storage sized around the accelerator
GPU use cases
Anything that parallelises well finishes sooner on a GPU — and finishing sooner is what you are actually buying.
Model training and inference
Simulation and analysis
3D rendering and visualisation
Video encoding and processing
Instance creation, storage, networking and quota — the same knowledge base covers everything GPU instances will build on.
Frequently asked questions about Antyxsoft GPUs
Are Antyxsoft GPUs available today?
Not yet. GPU products are not generally available at this time — support for GPU instances is being introduced soon. Join the waitlist and we will contact you as capacity opens in your region.
Which workloads are cloud GPUs suited to?
GPU instances accelerate workloads that rely on parallel processing: machine learning training and inference, scientific computing, 3D rendering and visualisation, and video encoding.
Can I customise a GPU instance?
Yes. GPU instances will offer flexible configuration options so the vCPU, memory and storage around the GPU can be matched to the workload.
How will GPU usage be monitored?
Real-time metrics and performance monitoring are included, so GPU utilisation can be tracked and optimised from the same control panel as the rest of your infrastructure.
Guides for GPU workloads
Visit the blog →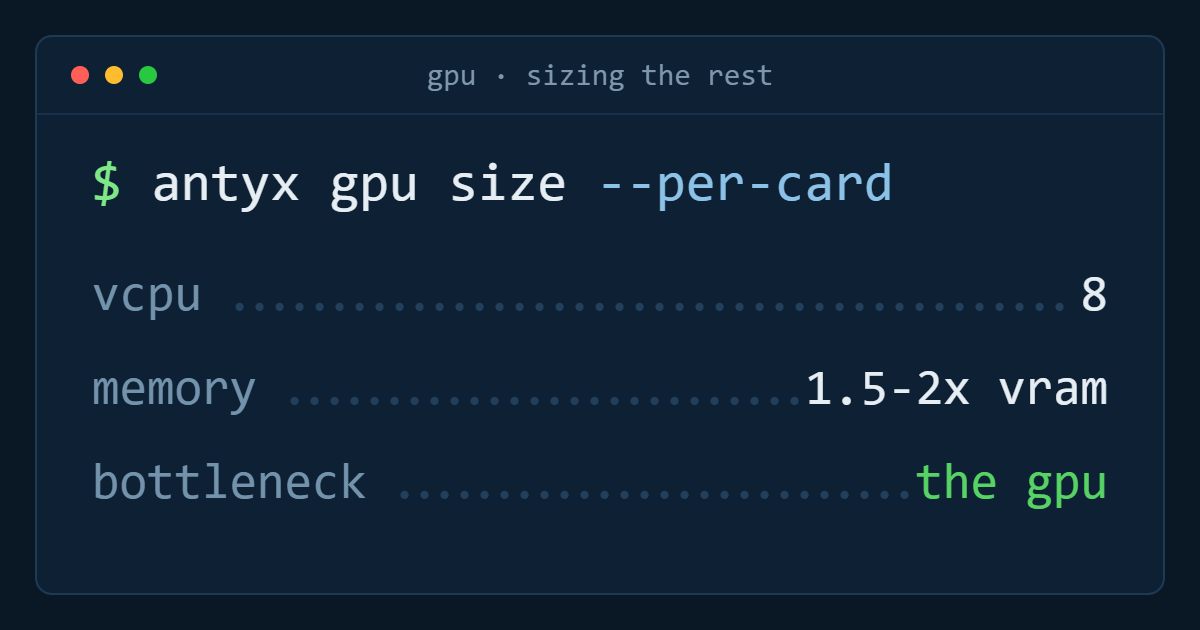
Sizing a GPU instance: what to put around the accelerator
vCPU, memory and NVMe decide whether the GPU ever reaches full utilisation. The numbers to start from.
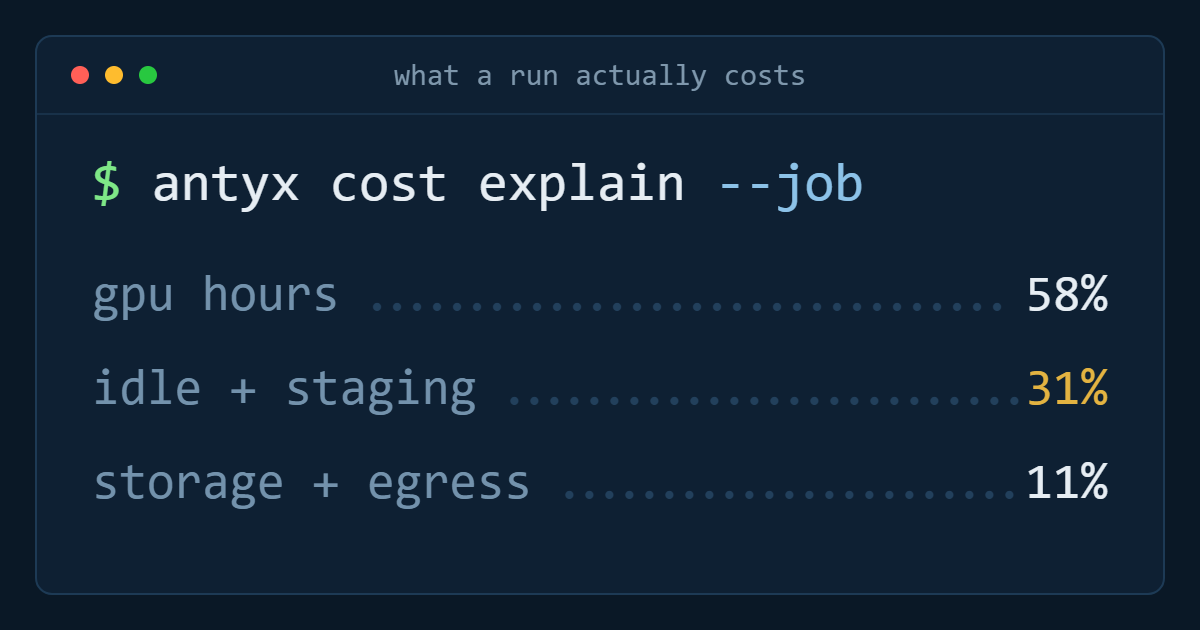
What a training run actually costs
The hourly rate is rarely more than half the bill. The five line items that make up the rest.
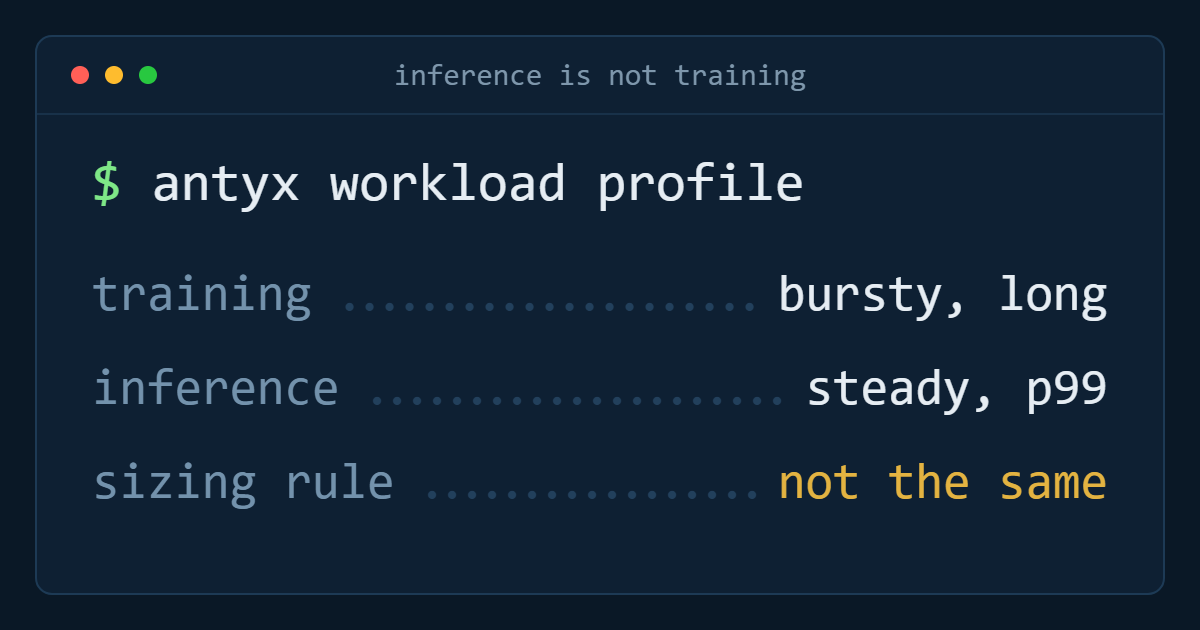
Inference is not training: sizing for serving
Memory and KV cache set your concurrency ceiling — not the compute you sized the training run on.
Be first in line for GPU capacity
Tell us what you plan to run and we will reach out the moment your region opens.